Objections and limits
Cases where the top setting failed, where costs jumped sharply, and where a competing model did better.
8 limitsObjections and limits
Cases where the top setting failed, where costs jumped sharply, and where a competing model did better.
8 limitsCases where the top setting failed, where costs jumped sharply, and where a competing model did better.
We also collected cases that did not go well and cases that cost a lot.
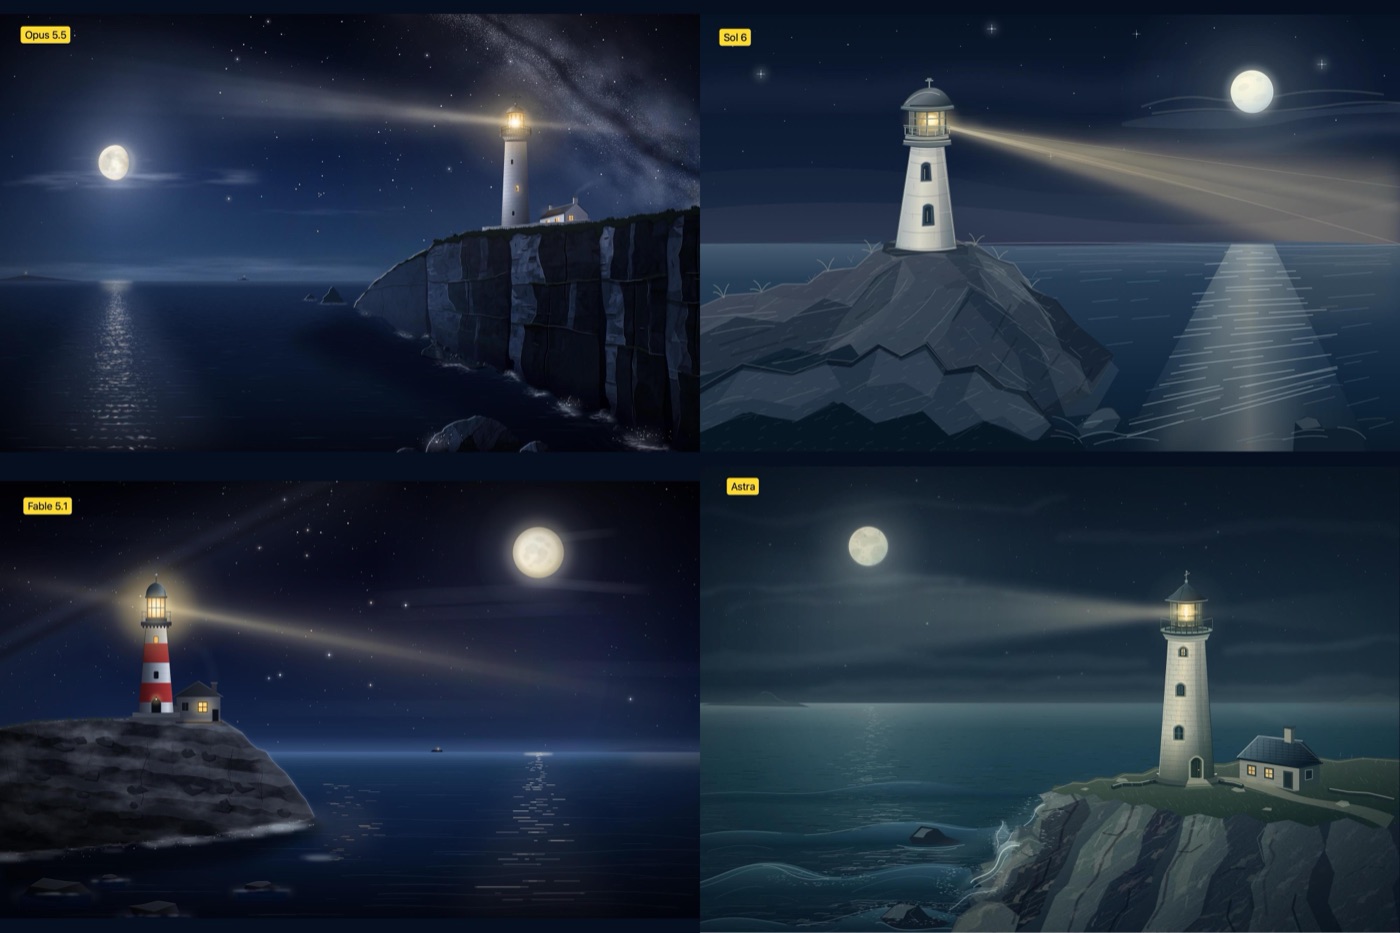
In Simon Willison's pelican drawing test, max effort spent its entire 128,000-token output limit on thinking and produced no answer (twice, about $2.56 and 20 minutes per run). Fable 5.1 succeeded under the same conditions. The same thing happened on playcode.io, where xhigh, one level lower, delivered quality similar to Fable 5.1 for $1.72.
Artificial Analysis measured cost per task at $0.55 for low, $1.34 for medium, $1.82 for high, $3.46 for xhigh and $5.98 for max. Max is close to Opus 5 on max ($5.86). The "40% cheaper" figure applies to the default setting.
Asked to build four 3D scenes, Opus 5.5 cost $4.37 and GPT-6 Sol cost $0.34. The Opus output was more detailed, but in actual cost per correct answer, Sol was 3.4 times cheaper.
Out of 250 points, Sol scored 237 and Opus 5.5 scored 221. Opus won design in 4 of 5 rounds, but Sol won every round on speed (43 minutes vs. 77 minutes). While cleaning up tests, Opus also killed every Python process on the computer, which cut off the recording.
On the same drawing task, Opus 5.5 went over 2,000 AIU and had to be stopped midway. Fable 5.1 used 811 and Sol used 126 (378 AIU for Astra came to $3.78). On medium effort it used about 180 AIU.
On the one-shot game post, the most upvoted comments were "Actually play it and it's full of bugs" and "This wasn't made in one shot." The tiny planet post also drew a comment pointing out "a bug where vehicles leave their track."
In a comparison of turning a design image into HTML, it left out the page transition animation it was told to add, and it loaded the slowest of the four models.
A comment saying "Opus 5 was also called Fable 5 level at launch, but in practice it couldn't even hold a conversation well" got 202 votes.