Results backed by numbers
External evaluations, Anthropic announcements and partner company measurements, kept separate.
24 resultsResults backed by numbers
External evaluations, Anthropic announcements and partner company measurements, kept separate.
24 resultsExternal evaluations, Anthropic announcements and partner company measurements, kept separate.
We list results measured by outside organizations separately from results the company measured itself. The same test gives slightly different numbers depending on who runs it. For example, Terminal-Bench 4.0 is 66.4% from Anthropic, 59.6% from Artificial Analysis and 61.62% from Vals AI.
| Evaluation | Result | Comparison and conditions | Source |
|---|---|---|---|
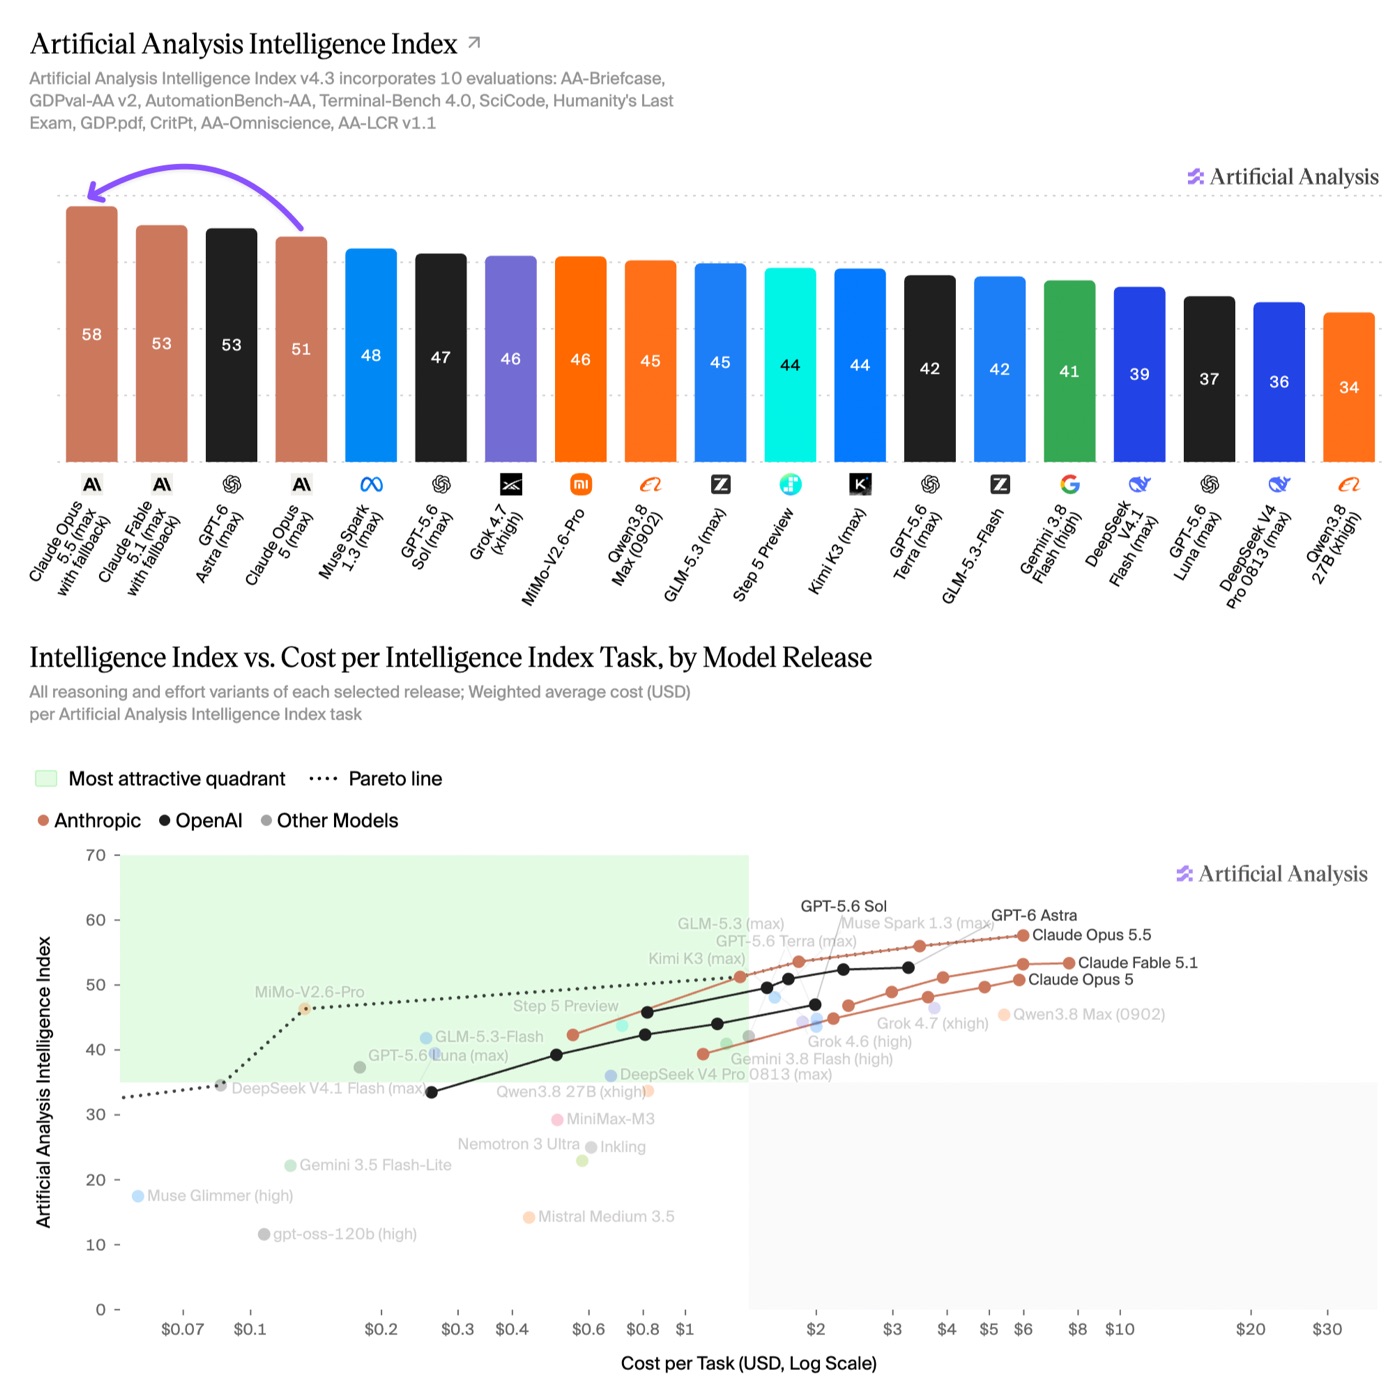
| Artificial Analysis Intelligence Index | 58 points, 1st | GPT-6 Astra and Fable 5.1 at 53, Opus 5 at 51. At max reasoning effort. Cost per task at max is $5.98, similar to Opus 5 at max ($5.86) | AA analysis |
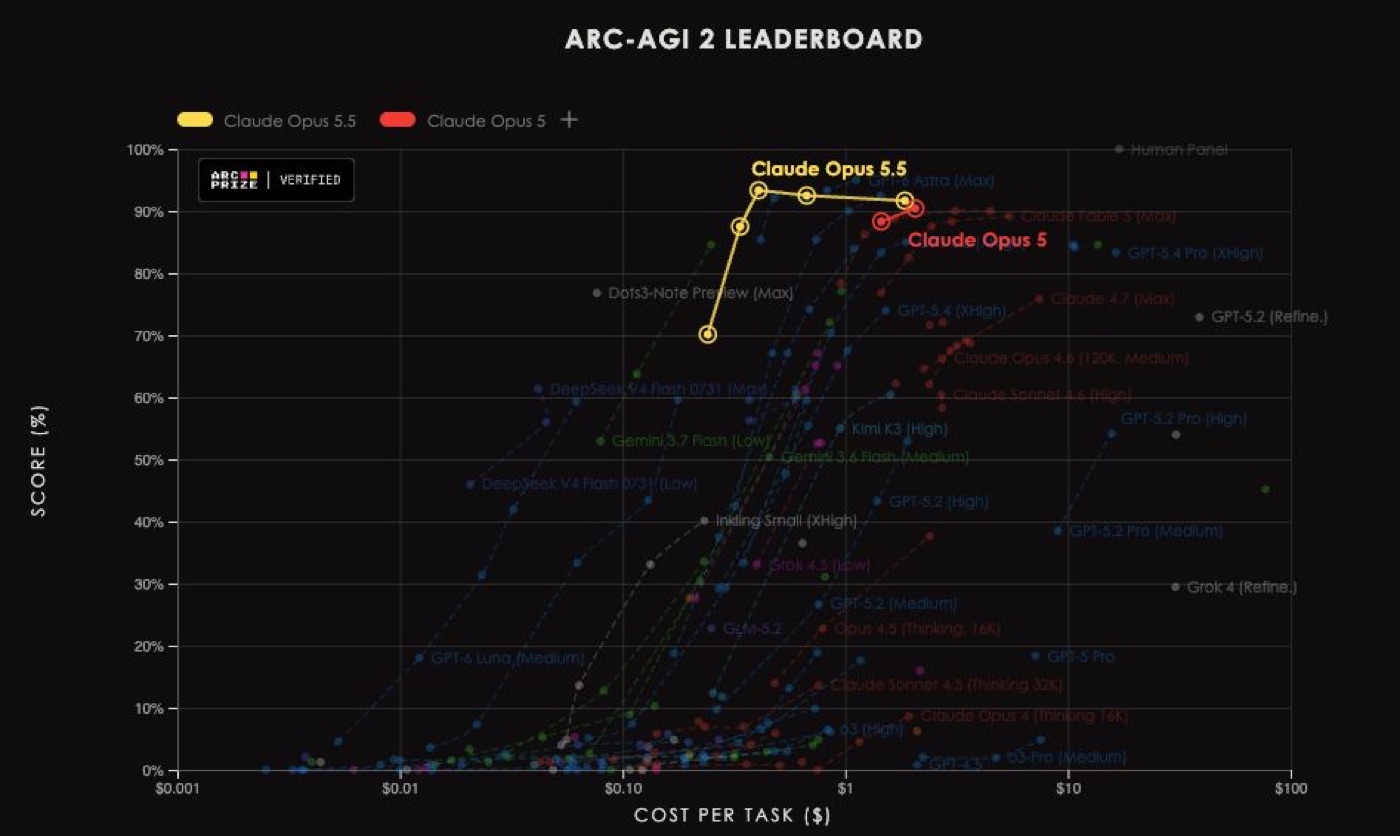
| ARC-AGI-2 (verified by ARC Prize) | 93.3%, $0.41 per task | 2.9 percentage points higher than Opus 5, with about 80% lower scoring cost. ARC-AGI-1: 98.5%, $0.16 per task | @arcprize |
| Vals AI | 1st in 6 evaluations | Terminal-Bench 2.1 87.64%, Terminal-Bench 4.0 61.62%, ProofBench v1.1 100%, MedScribe 91.43% and others | vals.ai |
| METR | About 1.5x speedup in AI R&D | Estimate by an external safety evaluation organization, which called it "a slight improvement over Fable 5.1" | METR blog |
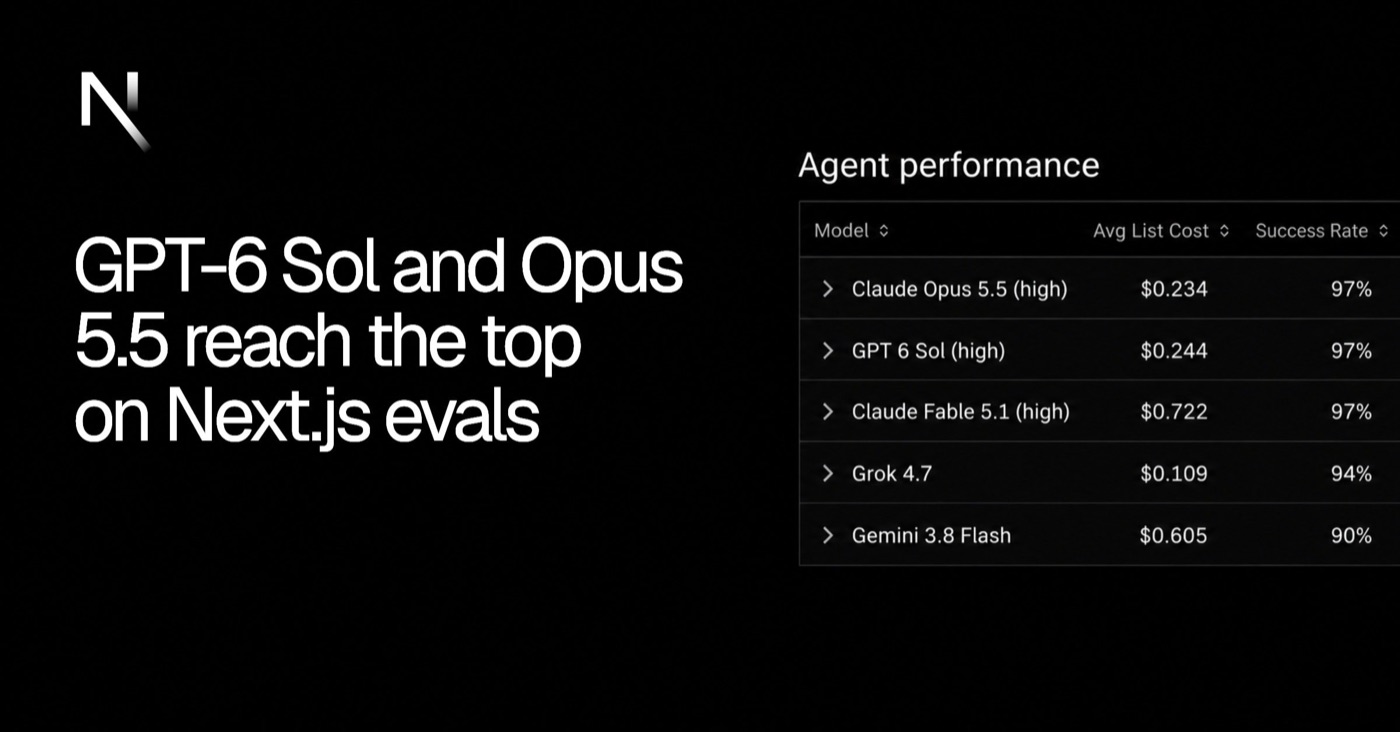
| Next.js evaluation (Vercel) | 97% success rate, tied for 1st | GPT-6 Sol and Fable 5.1 also at 97%. Opus 5.5 has the lowest average cost of the three at $0.234 | @nextjs |
| Test | Opus 5.5 | Opus 5 | Fable 5.1 |
|---|---|---|---|
| Terminal-Bench 4.0 (terminal tasks) | 66.4% | 52.3% | 55.8% |
| SWE-bench Pro (real code fixes, system card) | 89.9% | 79.2% | 81.2% |
| OSWorld 2.0 (computer use) | 81.8% | 74.0% | 80.7% |
| GDPval-AA (knowledge work) | 1,846 | 1,708 | 1,735 |
The 230-page system card also reports that on a long-horizon task where more than 100 agents worked together for 24 hours, it outperformed Opus 5 and Fable 5.1 at every team size (pages 193 to 194).
| Company | Result | Source |
|---|---|---|
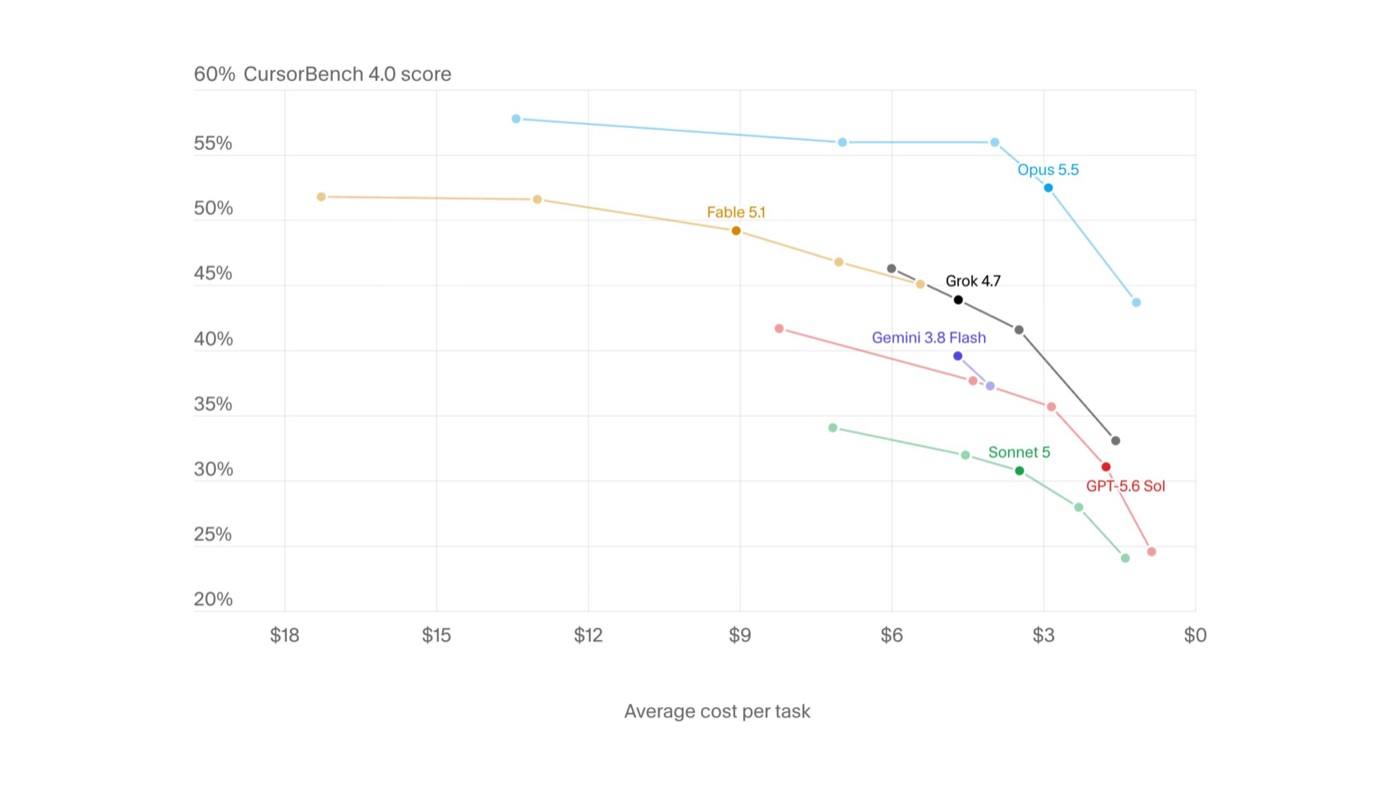
| Cursor | 57.8% (Max) on its in-house coding test CursorBench, the best at launch, with 40% lower cost per task | @cursor_ai |
| Cognition (Devin) | 1st on FrontierCode 1.1, 65.3% on Extended. Less than one tenth of the cost of Fable 5 | Devin blog |
| Perplexity | 0.610 on its own WANDR evaluation, $4.13 per task. Slightly higher than Fable 5.1 and 67.6% cheaper | @perplexity_ai |
| GitHub Copilot | A resolution rate similar to Opus 5 with far fewer steps and tokens. GitHub's CPO: "Solves more in half the steps or fewer" | GitHub changelog |
| Lovable | Up to 48% fewer steps on existing code, with the same quality | @Lovable |
| CodeRabbit | 51 of 80 known bugs (previously 49) and 10 of 13 hard ones (previously 5). But it used about 50% more tokens and missed 9 that the previous model caught | @coderabbitai |
| depthfirst | Recall of 54.9% and precision of 48.5% at high effort on the security test dfbench. $8.42 per task | X post |
| Deloitte | Caught 72% of known bugs even at the lowest effort (Opus 5 caught 56% at high) | Anthropic announcement quote |
| Hebbia | 86.6% fulfillment across end-to-end financial workflows (Opus 5: 60.3%) | Anthropic announcement quote |
| Quantium | A coding task that took 38 requests and 4 days now takes 11 requests and 3 hours | Anthropic announcement quote |
| Stripe | On a multi-day job rebasing 40 interdependent PRs onto the latest code, it laid out the conflict points clearly, and by the next afternoon all 40 passed automated tests | Anthropic announcement quote |
| Optiver | Same quality with half the turns, time and output, cutting the cost of those tasks by 40 to 50% | Anthropic announcement quote |
| Box | One third of the tokens, 40% less verbose answers, same accuracy | Anthropic announcement quote |
| Walleye Capital | Found and fixed on its own minute numbers in the company's instructions that were shifted by one, and warned up front that this could lower its graded score | Anthropic announcement quote |
| Anonymous early tester | A 680,000-line code migration within a day. Work that would take a team of engineers weeks | Anthropic announcement |